Introducing ExtractBench, the most comprehensive document extraction benchmark. Learn More →

LlamaParse vs Reducto

LlamaParse is the most complete and accurate document OCR platform for agents.

LlamaParse sits at the cost and accuracy frontier for both document parsing and information extraction from complex documents. For both, it delivers the highest accuracy at the most affordable price point.

Capabilities

LlamaParse vs Reducto: high-level comparison

Features

LlamaParse

Reducto

Accuracy

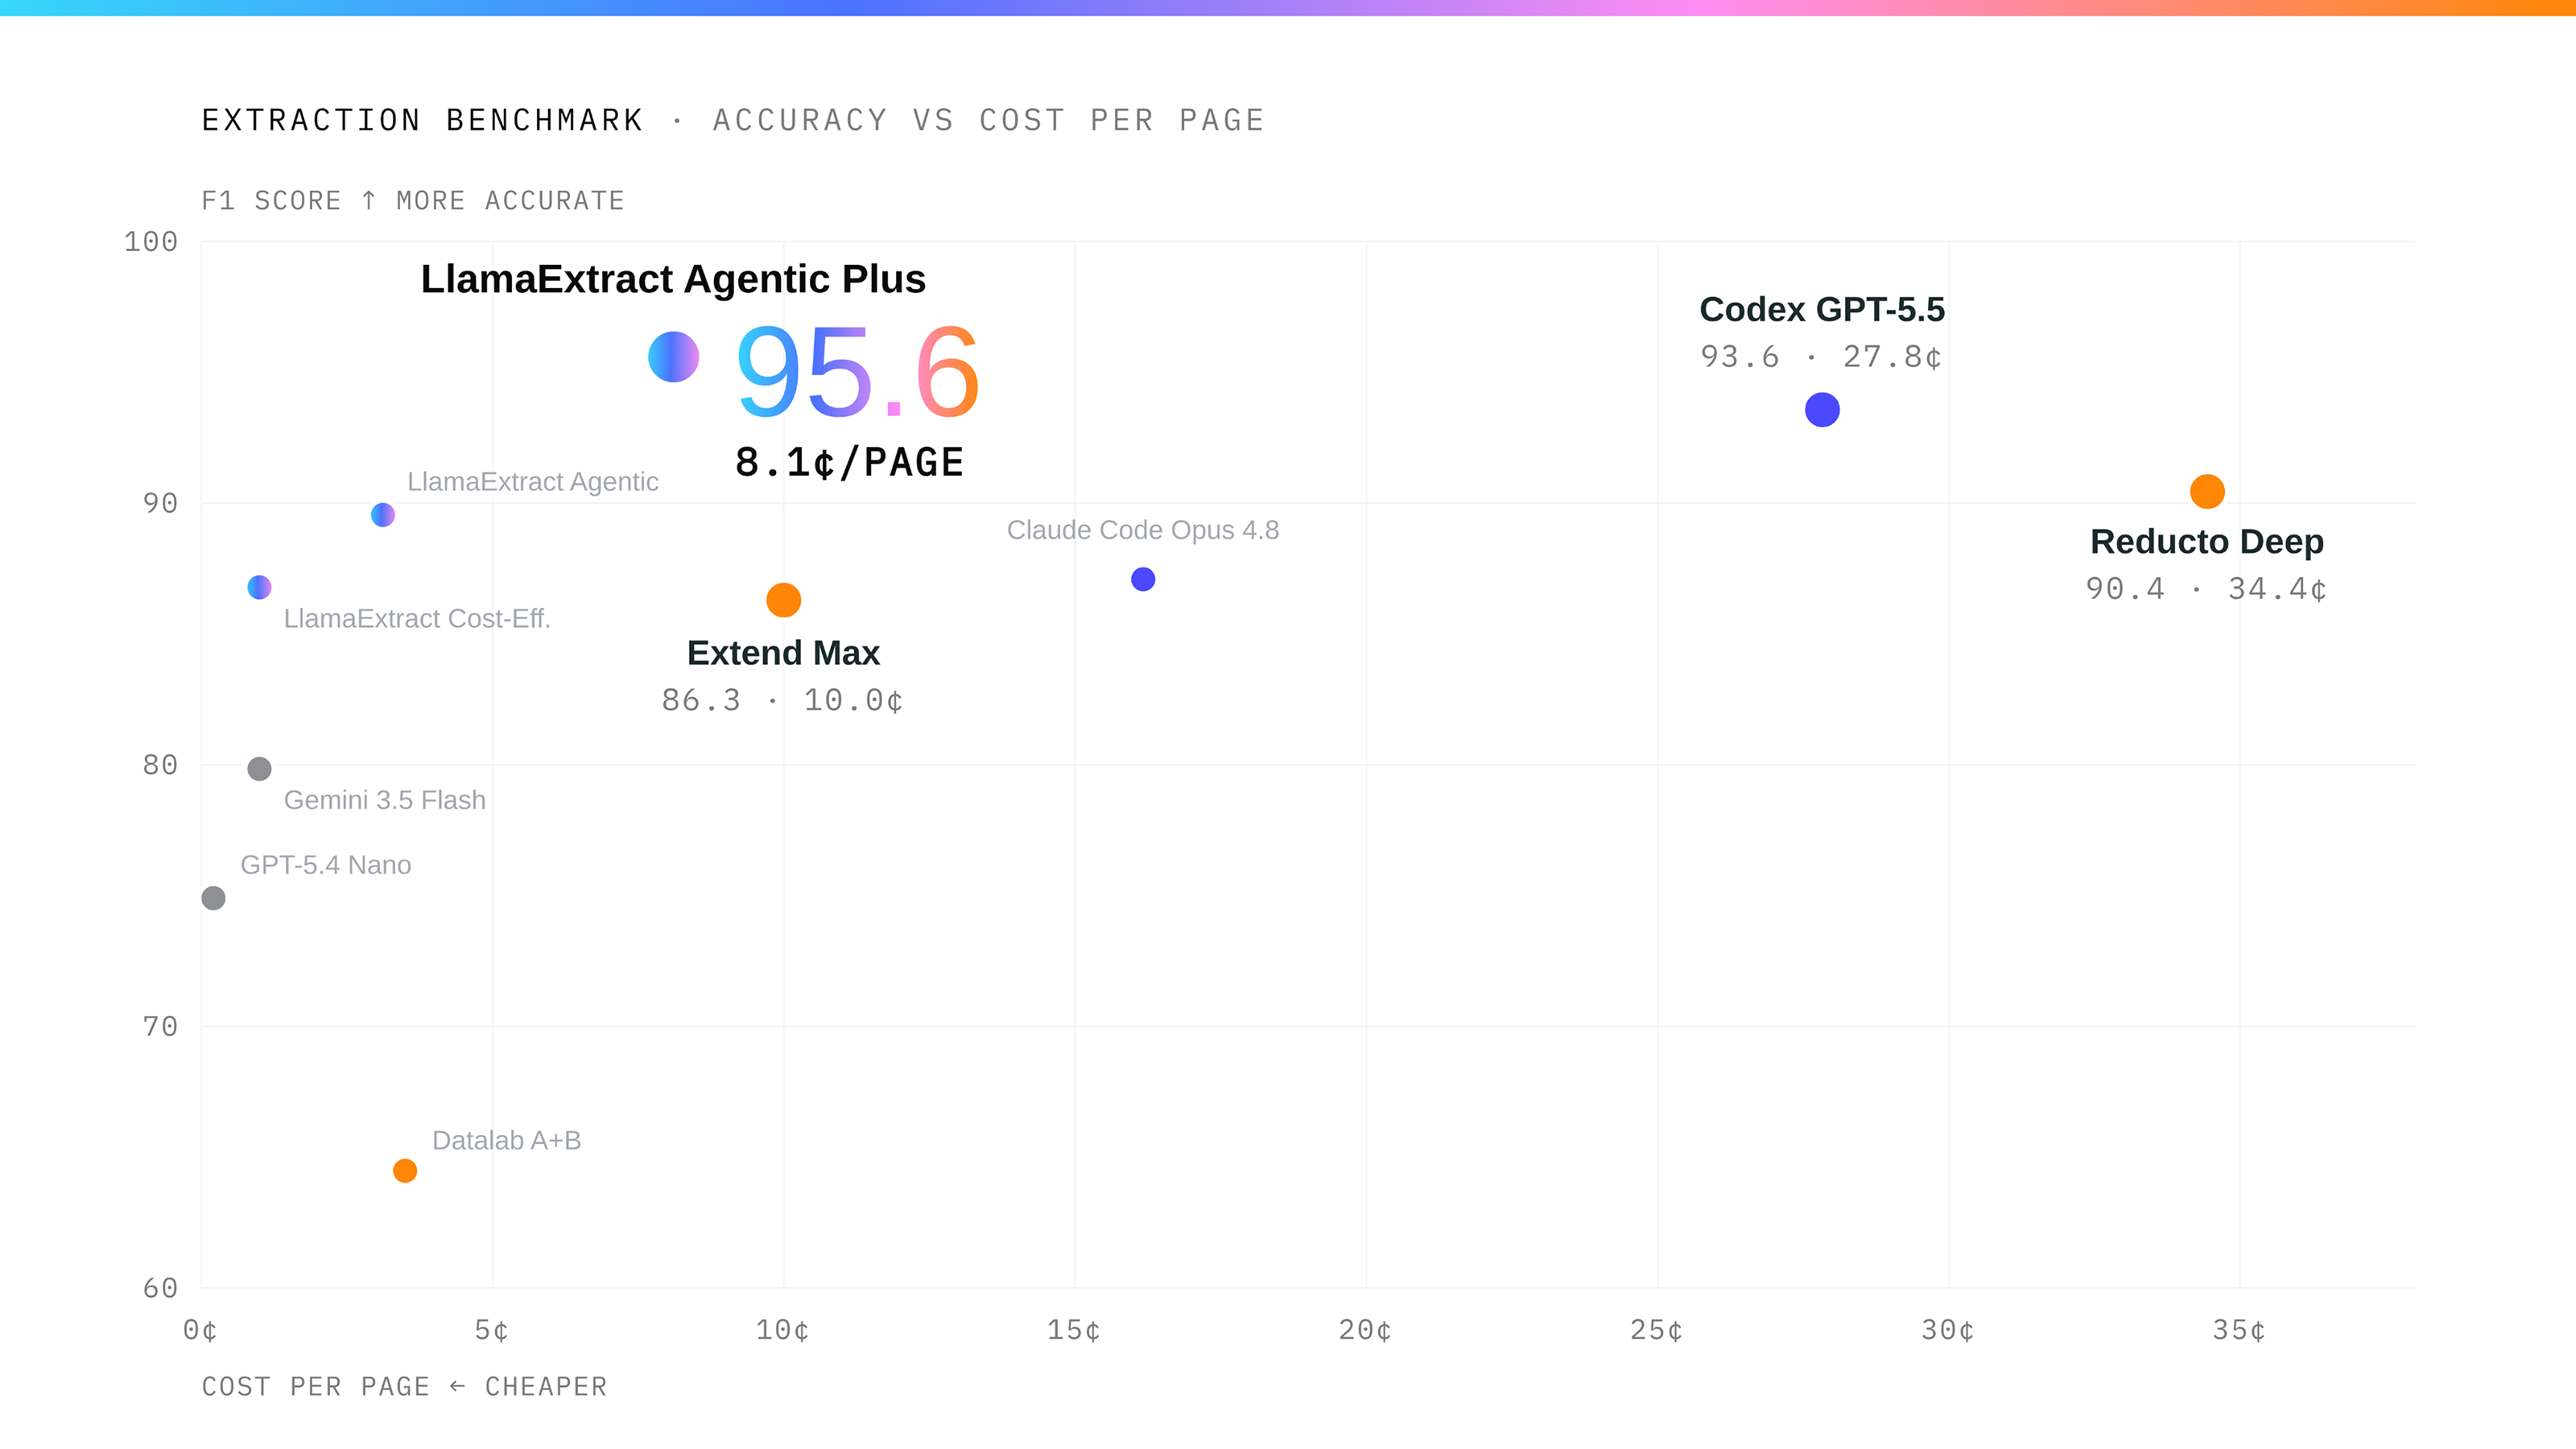
Accurate out of the box on a broad set of enterprise documents, with no templates and no per-document-type setup. First on industry-leading benchmarks like ParseBench (84.9) and ExtractBench (95.6%).

Overfitted for complex/dense tables in documents over hundred pages. Optimized for mass row extraction from long dense documents.

Parsing Cost

Agentic parsing is 1.25¢ per page, a flat rate. Four tiers are available, and the cost optimizer can route each page to the cheapest one that can handle it.

1¢ to 4¢ per page, with no tier below 1¢. Agentic parsing costs 2¢ to 4¢, and Reducto's classifier decides which. Against LlamaParse Agentic at a flat 1.25¢, that is 1.6× to 3.2× more expensive.

Platform scope

End-to-end document intelligence platform ready for agentic workloads: Parse, extract, classify, split, index, retrieve.

Parse, extract, split, classify, edit. No index or retrieval layer

Output & layout fidelity

Markdown, typed blocks with positions, spatial text, XLSX tables, tracked changes.

Markdown chunks. Tables as HTML, JSON, CSV, or markdown.

Benchmarks

ParseBench, ExtractBench - Complete Dataset, eval code, and methodology are open.

Micro1’s LongExtractBench is commissioned by Reducto. Only a partial subset of documents is open and it is not reproducible.

Extraction

Per document, per page, or per table row. Schemas to 3,200 fields. Confidence scores on every tier.

Per document. Schemas under 50 fields recommended. No confidence scores on Deep Extract.

Deployment

SaaS, private VPC, on-prem, and air-gapped. Local deployment of fine-tuned models with NO calls to external VLMs. OSS document parser LiteParse, runs on local CPUs, with no GPUs required.

SaaS, hybrid VPC, on-premises, air-gapped. Self-hosting requires customer-supplied H200 GPUs.

Input Coverage

130+ formats, including email, HTML, spreadsheets, and audio.

30+ formats. No email, HTML, or audio.

Zero training on your data by default

LlamaParse does not train models on your documents. That is the default on every plan, including the free tier. Training is an explicit opt-in that carries a credit discount, and it stays off unless you turn it on. Parsed results cache for 48 hours to make repeat requests cheap, and the cache can be disabled per request.

Reducto's position depends on the plan. Zero data retention is a Growth and Enterprise feature. On the self-serve tier that most teams evaluate on, their Terms of Use state that uploaded content "will be considered non-confidential and non-proprietary" and grant Reducto a license to use it to "develop new offerings or features."

Open and Verifiable Accuracy

On ExtractBench, LlamaExtract Agentic Plus ranks #1 at 95.6% value F1. Reducto Deep Extract ranks #3 at 90.4%. On ParseBench, LlamaParse Agentic ranks #1 at 84.9 against Reducto's 73.0.

We built both benchmarks and published everything needed to reproduce them: the documents, the ground-truth labels, the scoring code, and the methodology papers. Rerun them and you get the same numbers. Reducto has an entry on both.

Reducto's headline accuracy number comes from a benchmark it commissioned and whose ground-truth and grading methodology it wrote. Only 50 of its 225 documents are public, so the number cannot be reproduced.

Built for Real Enterprise Workloads

Short documents in volume are the bulk of enterprise document processing. Invoices, claims, statements, forms, and remittances are not edge cases. They are the workload. LlamaParse ranks #1 on ParseBench overall by being dependable across the whole range: simple pages, dense tables, charts, and scans. Reducto is overfitted to long documents with dense tables, so it does well on those and worse on everything else.

Transparent Pricing

LlamaParse charges per page across four tiers, from 0.125¢ to 5.6¢, matched to what the page contains: text-only, text-heavy, diagrams and images, or complex layouts. Each tier is a flat rate, and the cost optimizer can route each page to the cheapest tier that can handle it, so you do not pay one rate for a mixed workload.

Reducto charges 1¢ to 4¢ per page and has no tier below 1¢. You pick standard or agentic per request, and Reducto's classifier then decides whether the page bills as standard or complex. Agentic parsing lands somewhere between 2¢ and 4¢, and you find out which after the fact.

Our Agentic tier ranks first on ParseBench at 84.9 and costs a flat 1.25¢ a page. Reducto's agentic mode scores 73.0 and costs 2¢ to 4¢.

Our free tier renews at 10,000 credits every month, and credits are $1.25 per thousand. Reducto's is 15,000 credits once, limited to one trial per email domain.

State of the art parsing, wherever you deploy

We support parsing wherever your workload runs. LiteParse, our open-source parser, runs locally, entirely on CPUs with no vision model and no network call, and covers 50+ formats. Our fine-tuned models deploy on your own hardware, including GPU-constrained and bare-metal environments, with zero calls to external VLMs. Our hosted agentic tiers use current frontier vision models on the pages that need them. Parsing and extraction both expose tiers, so you trade cost against accuracy per request rather than per contract.

Enterprise deployment

LlamaParse is SOC 2 Type II, GDPR compliant, and HIPAA compliant with BAAs available. Run it hosted, in a private VPC, or in your own Kubernetes cluster on AWS, Azure, or Google Cloud, on standard nodes. We run a full EU region on every plan at the same price, staffed by engineers in European hours.
How to choose

Choose LlamaParse if

  • You process a range of document types and want one platform that handles all of them accurately.
  • You want to pay for the pages you process, not a floor for every document. We route each page to the cheapest tier that can handle it, with no per-document minimum.
  • You need to search across your documents and have agents act on them, not just get the text out.
  • You have European users or a European team, and want your data and your support in the same time zone.
  • Your documents have hundreds of fields to extract, and you would rather not split an application or a filing across a dozen calls.

Choose Reducto if

  • Your volumes are small enough that cost per page doesn't show up in your budget
  • You don't need to trade cost against accuracy, and one flat rate is fine

FAQ

01

Which is more accurate, LlamaParse or Reducto?

On the open benchmarks, LlamaParse scores higher on both tasks. Parsing: LlamaParse Agentic ranks #1 on ParseBench at 84.9 overall vs Reducto's 73.0. Extraction: LlamaParse Extract Agentic Plus ranks #1 on ExtractBench at 95.6% vs Reducto Deep Extract's 90.4%. Both benchmarks are fully public, so you can rerun them or test on your own documents.

02

Which is cheaper, LlamaParse or Reducto?

On parsing, LlamaParse. Our Agentic tier parses a page for a flat 1.25¢ against 2¢ to 4¢ for Reducto's agentic mode, and Reducto's classifier decides where in that range your page lands. LlamaParse scores higher on ParseBench too, 84.9 against 73.0, and can route each page to the cheapest tier that can handle it. On extraction, both platforms price per page across several tiers, so the answer depends on the accuracy level you need.

03

Is LlamaParse or Reducto better for complex tables and scanned documents?

Both are strong here, and this is where you should test your own document mix. LlamaParse leads ParseBench's tables category (90.7 vs 80.4) and is built for consistency across a whole workload; Reducto performs well on long documents with merged cells and nested headers. Run both on a representative sample, not a showcase sample.

Start parsing your first PDF today

LlamaParse gets you from raw unstructured data to structured markdown — fast.