OCRia-1
A 4-billion-parameter vision-language model for document parsing, with a focus on complex tables, charts, and mathematical notation.
- ParseBench overall
- 87.4 /100
- Model parameters
- 4B
Persona
Industry
Use cases
A 4-billion-parameter vision-language model for document parsing, with a focus on complex tables, charts, and mathematical notation.
Open evaluation
Document parsing
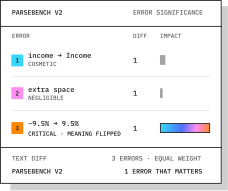
Tests tables, charts, text, formatting, and visual grounding using human-verified pages and deterministic evaluation rules.
Structured extraction
Tests schema-guided extraction across 370 enterprise documents, measuring value accuracy, record completeness, source grounding, and cost.
ExtractBench extension
Extends ExtractBench with six long-tail extraction challenges. A separate synthetic dataset tests conventions, domain rules, drawn relations, and complex charts.
These benchmarks are built and maintained by LlamaIndex. We evaluate our own systems alongside others and publish the datasets and evaluation code for inspection and reproduction.
Architecture, training, and evaluation of our 4B document parsing model.
Six challenges in the long tail of extraction, and how we built the data to test them.
Evaluating value accuracy, completeness, grounding, and measured cost.
Evaluating document parsing across tables, charts, content, formatting, and grounding.
4 selected publications
Open resources
Run the evaluations, inspect the data, or build with our open-source document tools.