LlamaParse vs Azure Document Intelligence
LlamaParse is the agentic document processing platform at the frontier of price-performance built for accurate extraction from complex documents. Azure Document Intelligence is a legacy OCR service, built for the Azure ecosystem.
Last updated: October 28, 2026
Capabilities
LlamaParse vs Azure Document Intelligence: at a glance
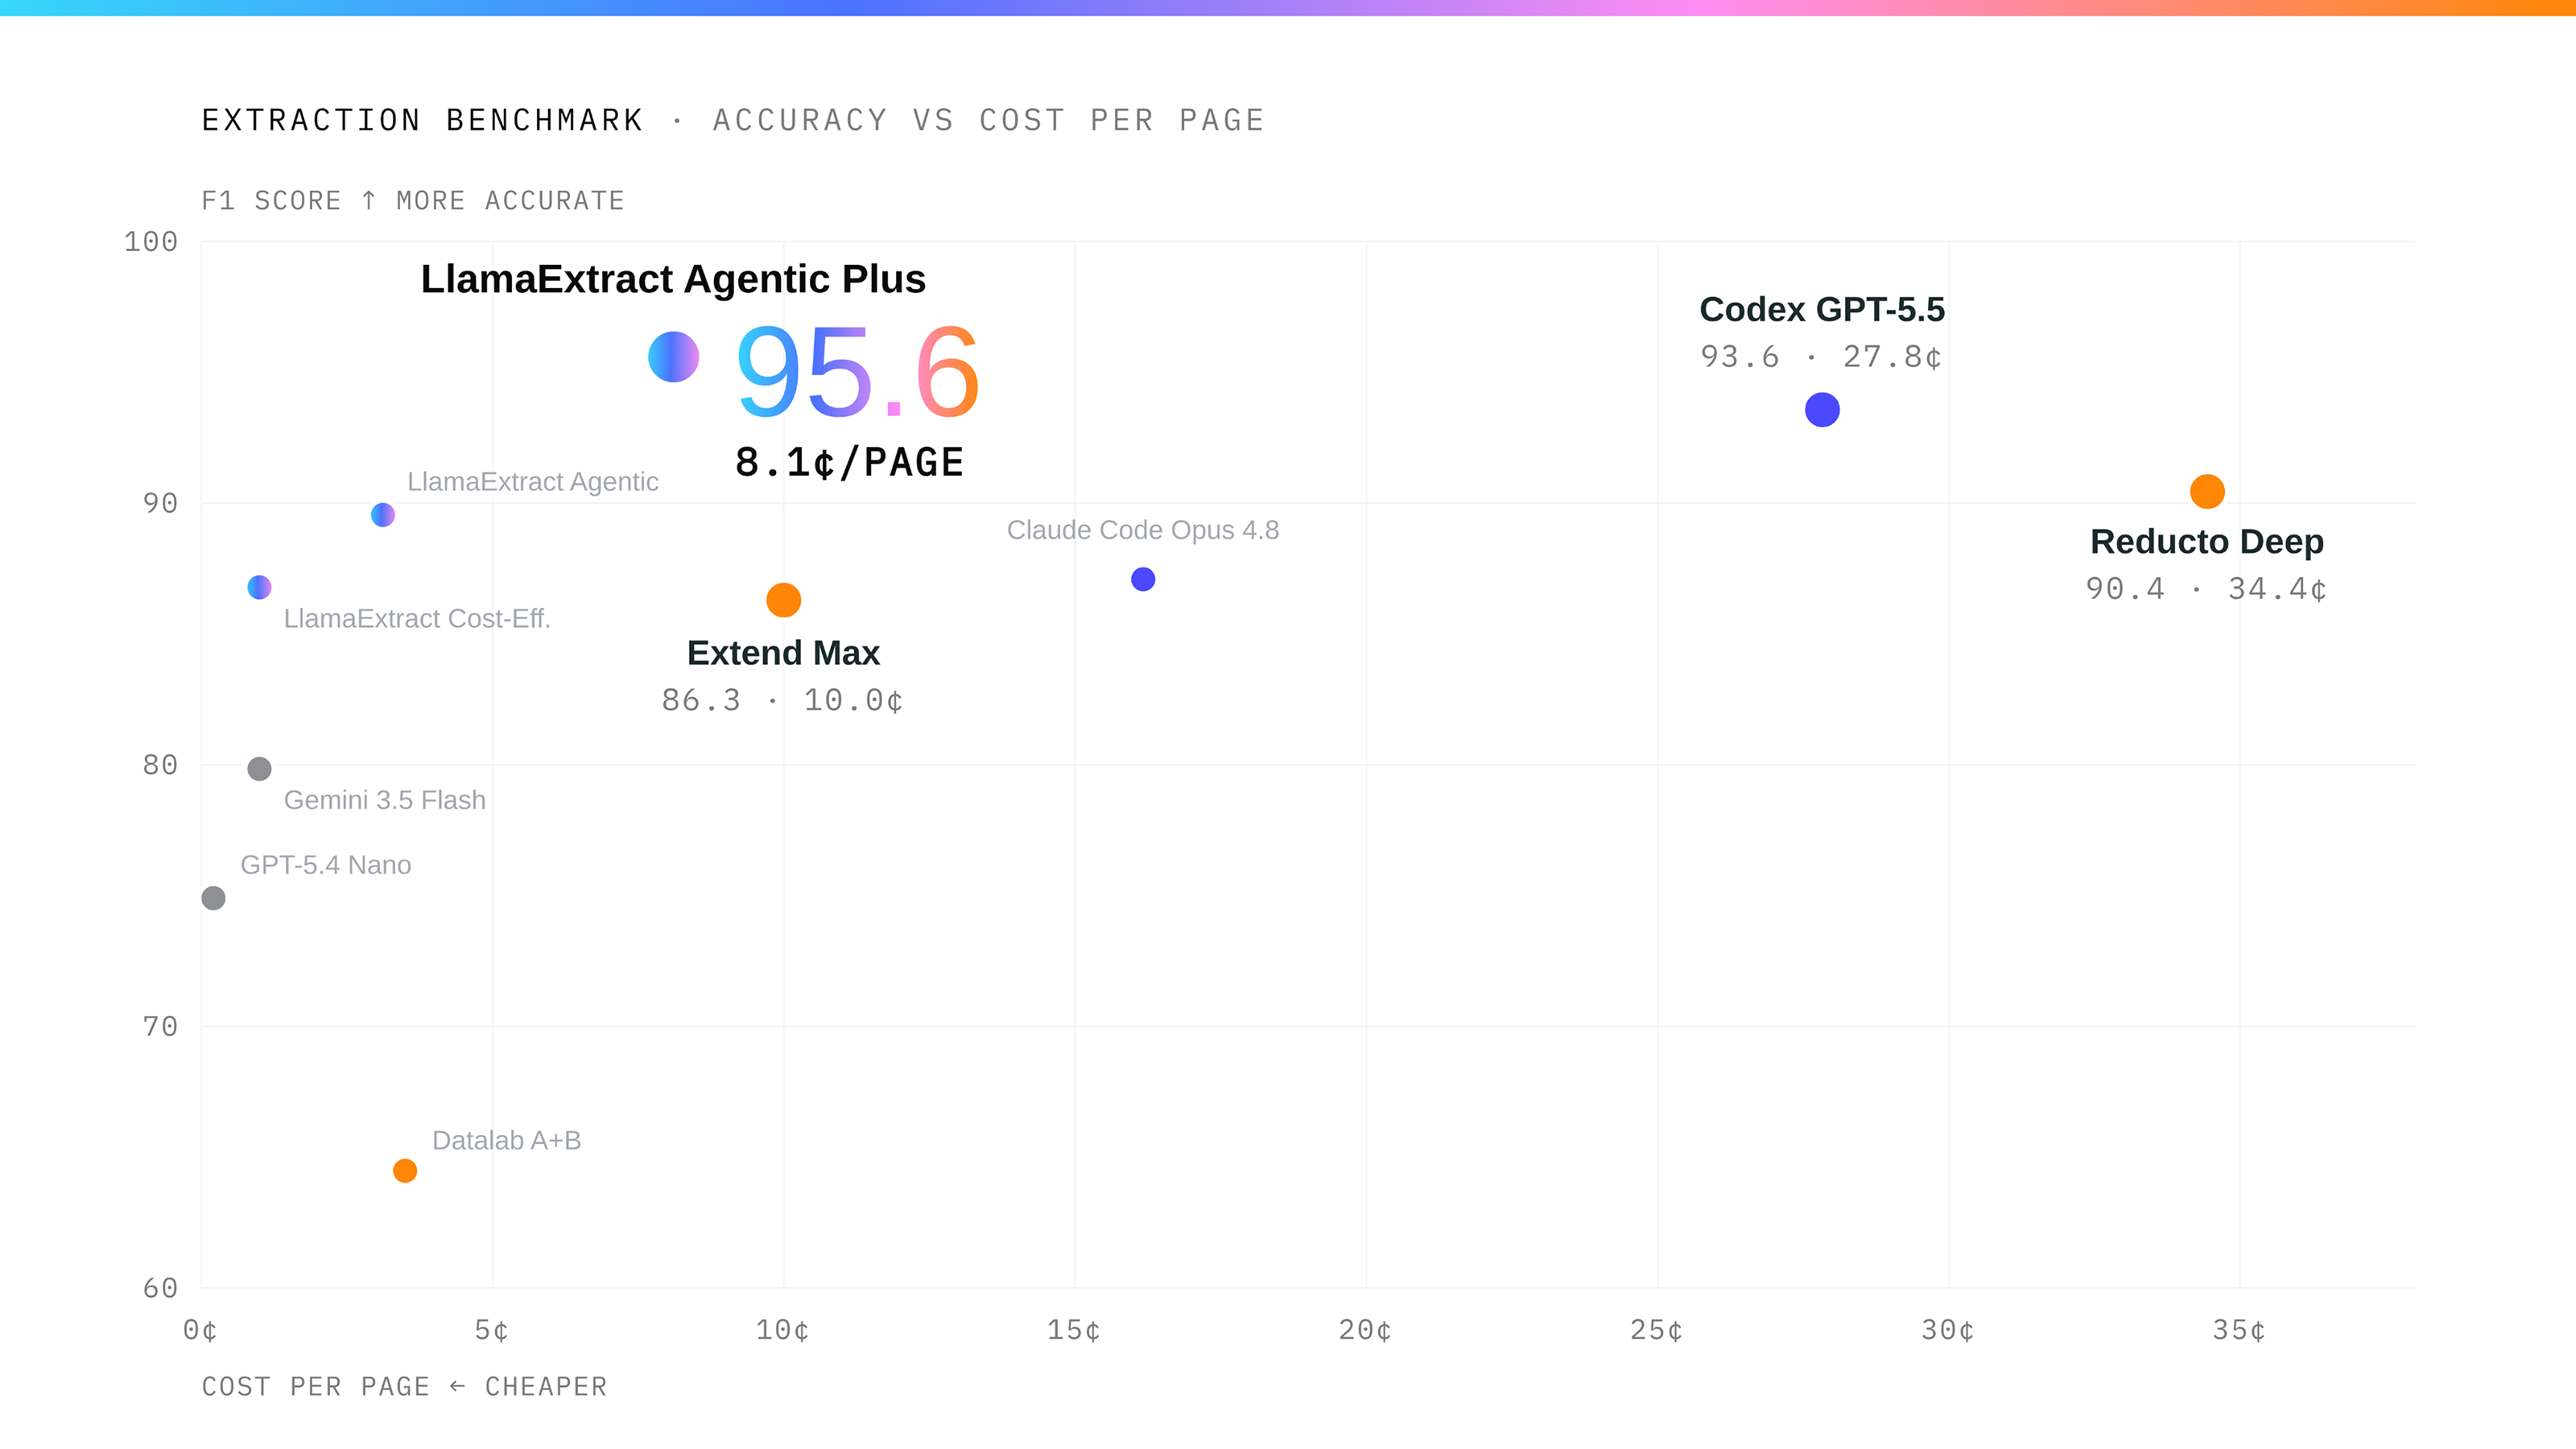
LlamaParse is more accurate than Azure Document Intelligence in every ParseBench category, extracts any fields you define without training a model, and costs $10 per 1,000 pages for parsing and extraction to Azure’s $20 to $30.
Features | LlamaParse | Azure Document Intelligence |
|---|---|---|
| Parsing accuracy | Scores 86.61 on ParseBench and leads Azure in every category, 93.37 to 86.00 on tables and 90.19 to 1.56 on charts. | Reads text and tables well, but cannot read charts and loses half the formatting: 1.56 on charts and 51.93 on formatting in ParseBench. |
| Extraction accuracy on complex documents | Extracts any fields you define as one JSON result, including records that span pages, with no model to train, and scores 96.17% on ExtractBench. | Extracts fixed field sets through prebuilt models, or custom models trained on labeled documents; adding fields through Query Fields costs an extra $10 per 1,000 pages. |
| Automating review | Scores and cites every extracted value, so reviewers only check the uncertain ones. | Scores some fields, depending on the model; not every extracted value gets a confidence score. |
| Price for parsing and extraction | Costs $10 per 1,000 pages at the entry tier and $31.25 at the higher tier, parsing and extraction included. | Costs $10 per 1,000 pages for Layout, $20 with Query Fields, and $30 for a custom extraction model, before add-ons. |
| File formats | Handles 130+ formats, including PDFs, Word, PowerPoint, Excel and CSV, and extracts straight from Excel and CSV cells. | Read and Layout take PDFs, images, Office files and HTML, but table analysis is unsupported for Excel, and extraction models take PDFs and images only. |
| Enterprise deployment | Runs hosted, as a dedicated deployment, in your own cloud, or on-premises. | Runs in Azure, or in containers for supported models; disconnected deployments need access approval and a commitment plan. |
| Connectors | Pulls files from Google Drive, SharePoint, S3 and Confluence. | No built-in connectors; files arrive by URL or upload. |
| ParseBench and ExtractBench are LlamaIndex benchmarks with public data and code. Scores are for Agentic Plus; the Azure result is the Layout model. Prices are USD per 1,000 PDF pages, before add-ons or discounts; Azure rates are East US. | ||
Parses the most complex documents
LlamaParse parses nested and multi-page tables, charts, merged headers, dense financial statements, scans, handwriting and photographed pages, across 130+ file formats. It is the most accurate parser on ParseBench overall and leads Azure Document Intelligence in every category, by the widest margin on charts: 90.19 to 1.56.
Extracts the data you need
Define the fields you need in a schema, such as policy number, deductible and each claim line item, and LlamaParse Extract returns them as structured JSON in one result, including records that span pages and data read straight from Excel and CSV cells. Change the schema when requirements change. Azure’s custom models need labeled training documents, and its prebuilt models return fixed field sets.
Confidence scores and citations on every value
Every value LlamaParse extracts carries a confidence score and a citation to the source text, so reviewers check only the low-confidence values and accept the rest. Azure scores some fields, depending on the model.
Lower price at every level
Text parsing starts at $1.25 per 1,000 PDF pages to Azure Read’s $1.50. Parsing on Cost Effective costs $3.75 and scores 78.02 on ParseBench, to Azure Layout’s $10 and 59.64. Parsing and extraction cost $10 at the entry tier and $31.25 at the higher tier, to $20 for Layout with Query Fields and $30 for a custom extraction model.
Connectors and fraud checks built in
Pull files straight from Google Drive, SharePoint, S3 and Confluence, with no upload code to write. Verify (preview) flags documents that show signs of tampering or fabrication, with the evidence behind each finding.
Runs in your own cloud or on-premises
LlamaParse is hosted in North America and the EU, or as a dedicated deployment run by LlamaIndex. Enterprise customers run it in their own Azure, AWS or Google Cloud account, or on-premises. LlamaIndex has a SOC 2 Type II audit, offers BAAs on Enterprise, and does not train on customer data by default. Azure Document Intelligence runs in Azure, or in containers for supported models; disconnected deployments need access approval and a commitment plan.
FAQ
01
What’s the difference between LlamaParse and Azure Document Intelligence?
01
What’s the difference between LlamaParse and Azure Document Intelligence?
LlamaParse parses 130+ file formats and the most complex layouts, including nested and multi-page tables, charts, merged headers, scans and handwriting, then extracts any fields you define and scores every value for confidence. Azure Document Intelligence extracts fixed field sets through prebuilt models, or custom models you train.
02
Which has higher parsing accuracy, LlamaParse or Azure Document Intelligence?
02
Which has higher parsing accuracy, LlamaParse or Azure Document Intelligence?
LlamaParse, in every ParseBench category. Agentic Plus scores 86.61 overall and Cost Effective 78.02, compared with 59.64 for Azure Document Intelligence Layout.
03
Which costs less, LlamaParse or Azure Document Intelligence?
03
Which costs less, LlamaParse or Azure Document Intelligence?
LlamaParse. Parsing costs $3.75 per 1,000 PDF pages on Cost Effective, compared with $10 for Azure Layout, and Cost Effective scores 78.02 on ParseBench to Layout’s 59.64. Parsing and extraction cost $10 at the entry tier and $31.25 at the higher tier, compared with $20 for Azure Layout with Query Fields and $30 for a custom extraction model.
04
Which is better for complex tables and scanned documents?
04
Which is better for complex tables and scanned documents?
LlamaParse. Agentic Plus scores 93.37 on tables and 90.19 on charts in ParseBench, compared with 86.00 and 1.56 for Azure Layout.
05
Can LlamaParse extract data directly from Excel workbooks?
05
Can LlamaParse extract data directly from Excel workbooks?
Yes. LlamaParse reads .xlsx, .xls and .csv cells directly into the fields you define, with no PDF conversion.
06
Does LlamaParse support confidence scores and citations?
06
Does LlamaParse support confidence scores and citations?
Yes. Every extracted value gets a confidence score and a citation to its source text.
07
Can LlamaParse run in Azure or on-premises?
07
Can LlamaParse run in Azure or on-premises?
Yes. Enterprise customers run LlamaParse in their own Azure, AWS or Google Cloud account, or on-premises. LlamaParse is also hosted in North America and the EU, or as a dedicated deployment run by LlamaIndex.
08
Can I migrate from Azure Document Intelligence to LlamaParse?
08
Can I migrate from Azure Document Intelligence to LlamaParse?
Yes. Express the fields you need as a JSON Schema, replace your parsing or extraction API calls, and map LlamaParse’s output into your workflow.
Explore more comparisons