Most document AI platforms make you pick between convenience and control. LlamaParse doesn't. It's built to run wherever your documents need to live: as a fully managed API, inside your own cloud account, or in your own data center. And you choose who runs the models behind it. The same parsing and extraction engine works across every setup, so your deployment fits your security, compliance, and infrastructure requirements, not the other way around.
That flexibility matters most when document pipelines move into production. Where will your documents live? What needs to run in your environment? How much infrastructure does your team want to own? LlamaParse has an answer for each:
- SaaS: We run the platform and inference infrastructure.
- VPC (BYOC): You deploy the platform in your AWS, Azure, or Google Cloud account.
- On-prem: You run the platform in your own data center.
And running the platform yourself doesn’t have to mean signing up to run a fleet of GPUs. LlamaIndex can manage inference for you, giving you cost savings, immediate compute availability, and less operational overhead.
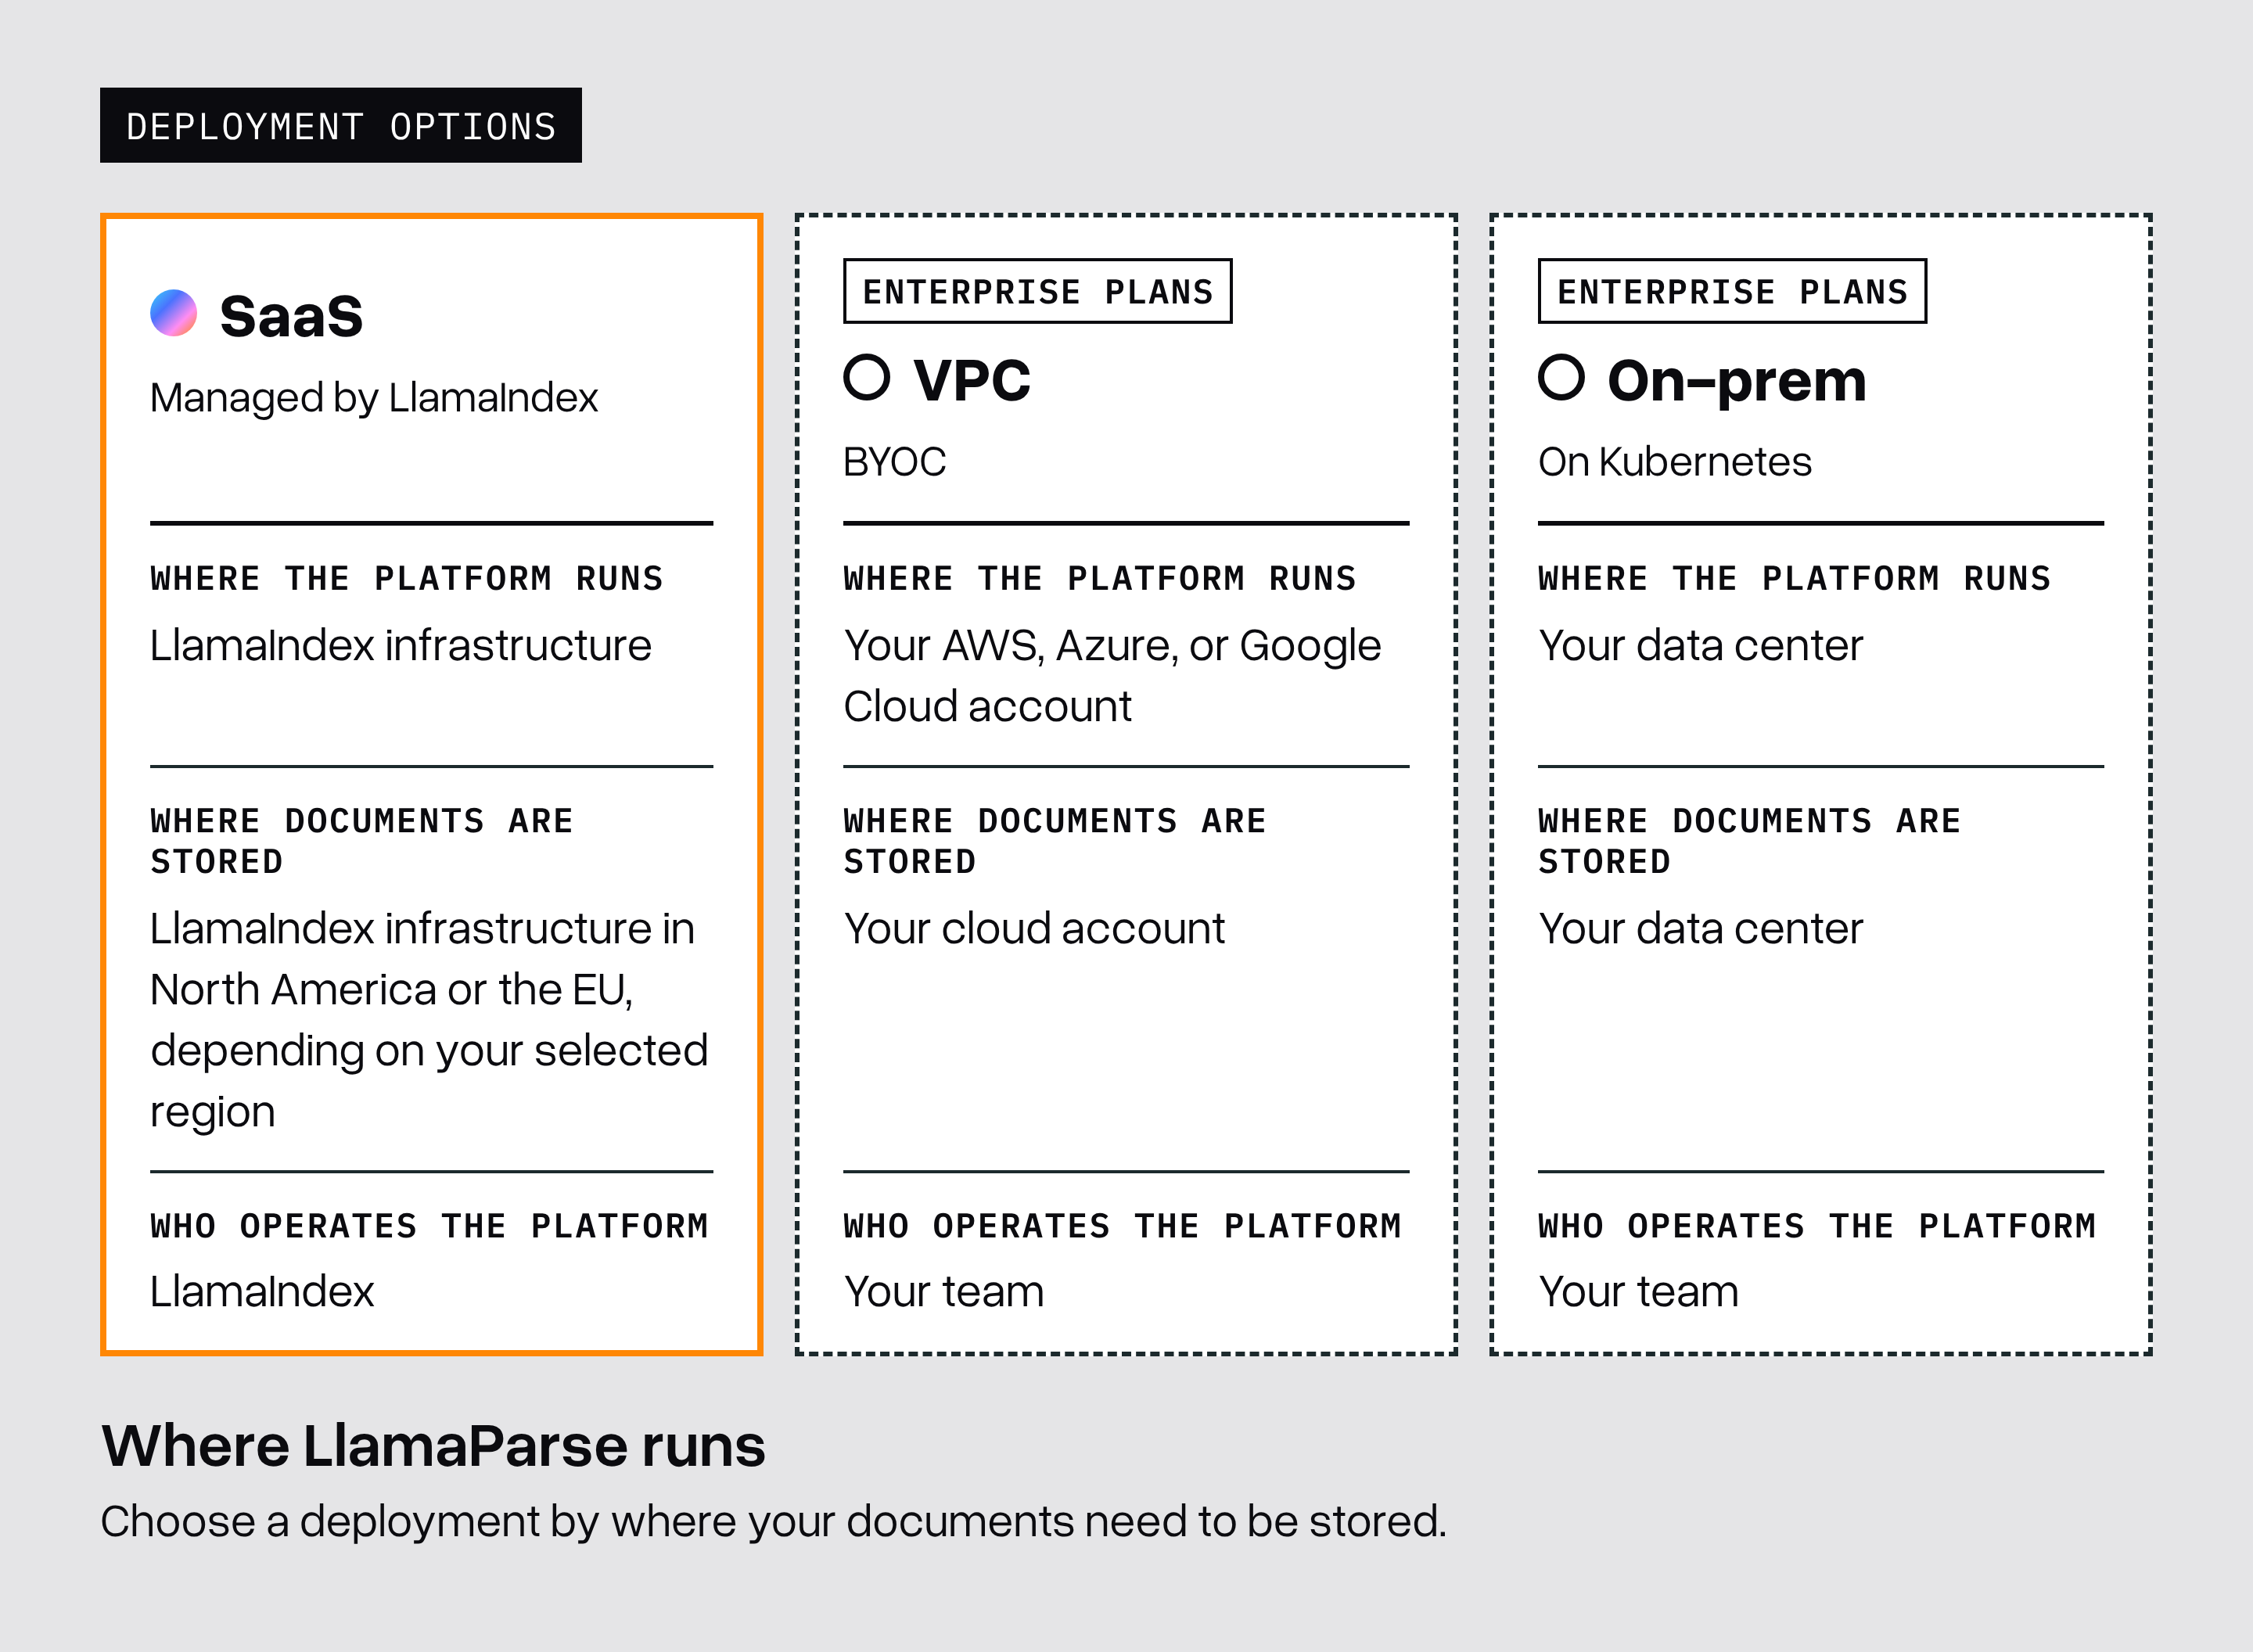
Below we'll walk through each deployment option, along with the benefits and considerations of each.
LlamaParse SaaS
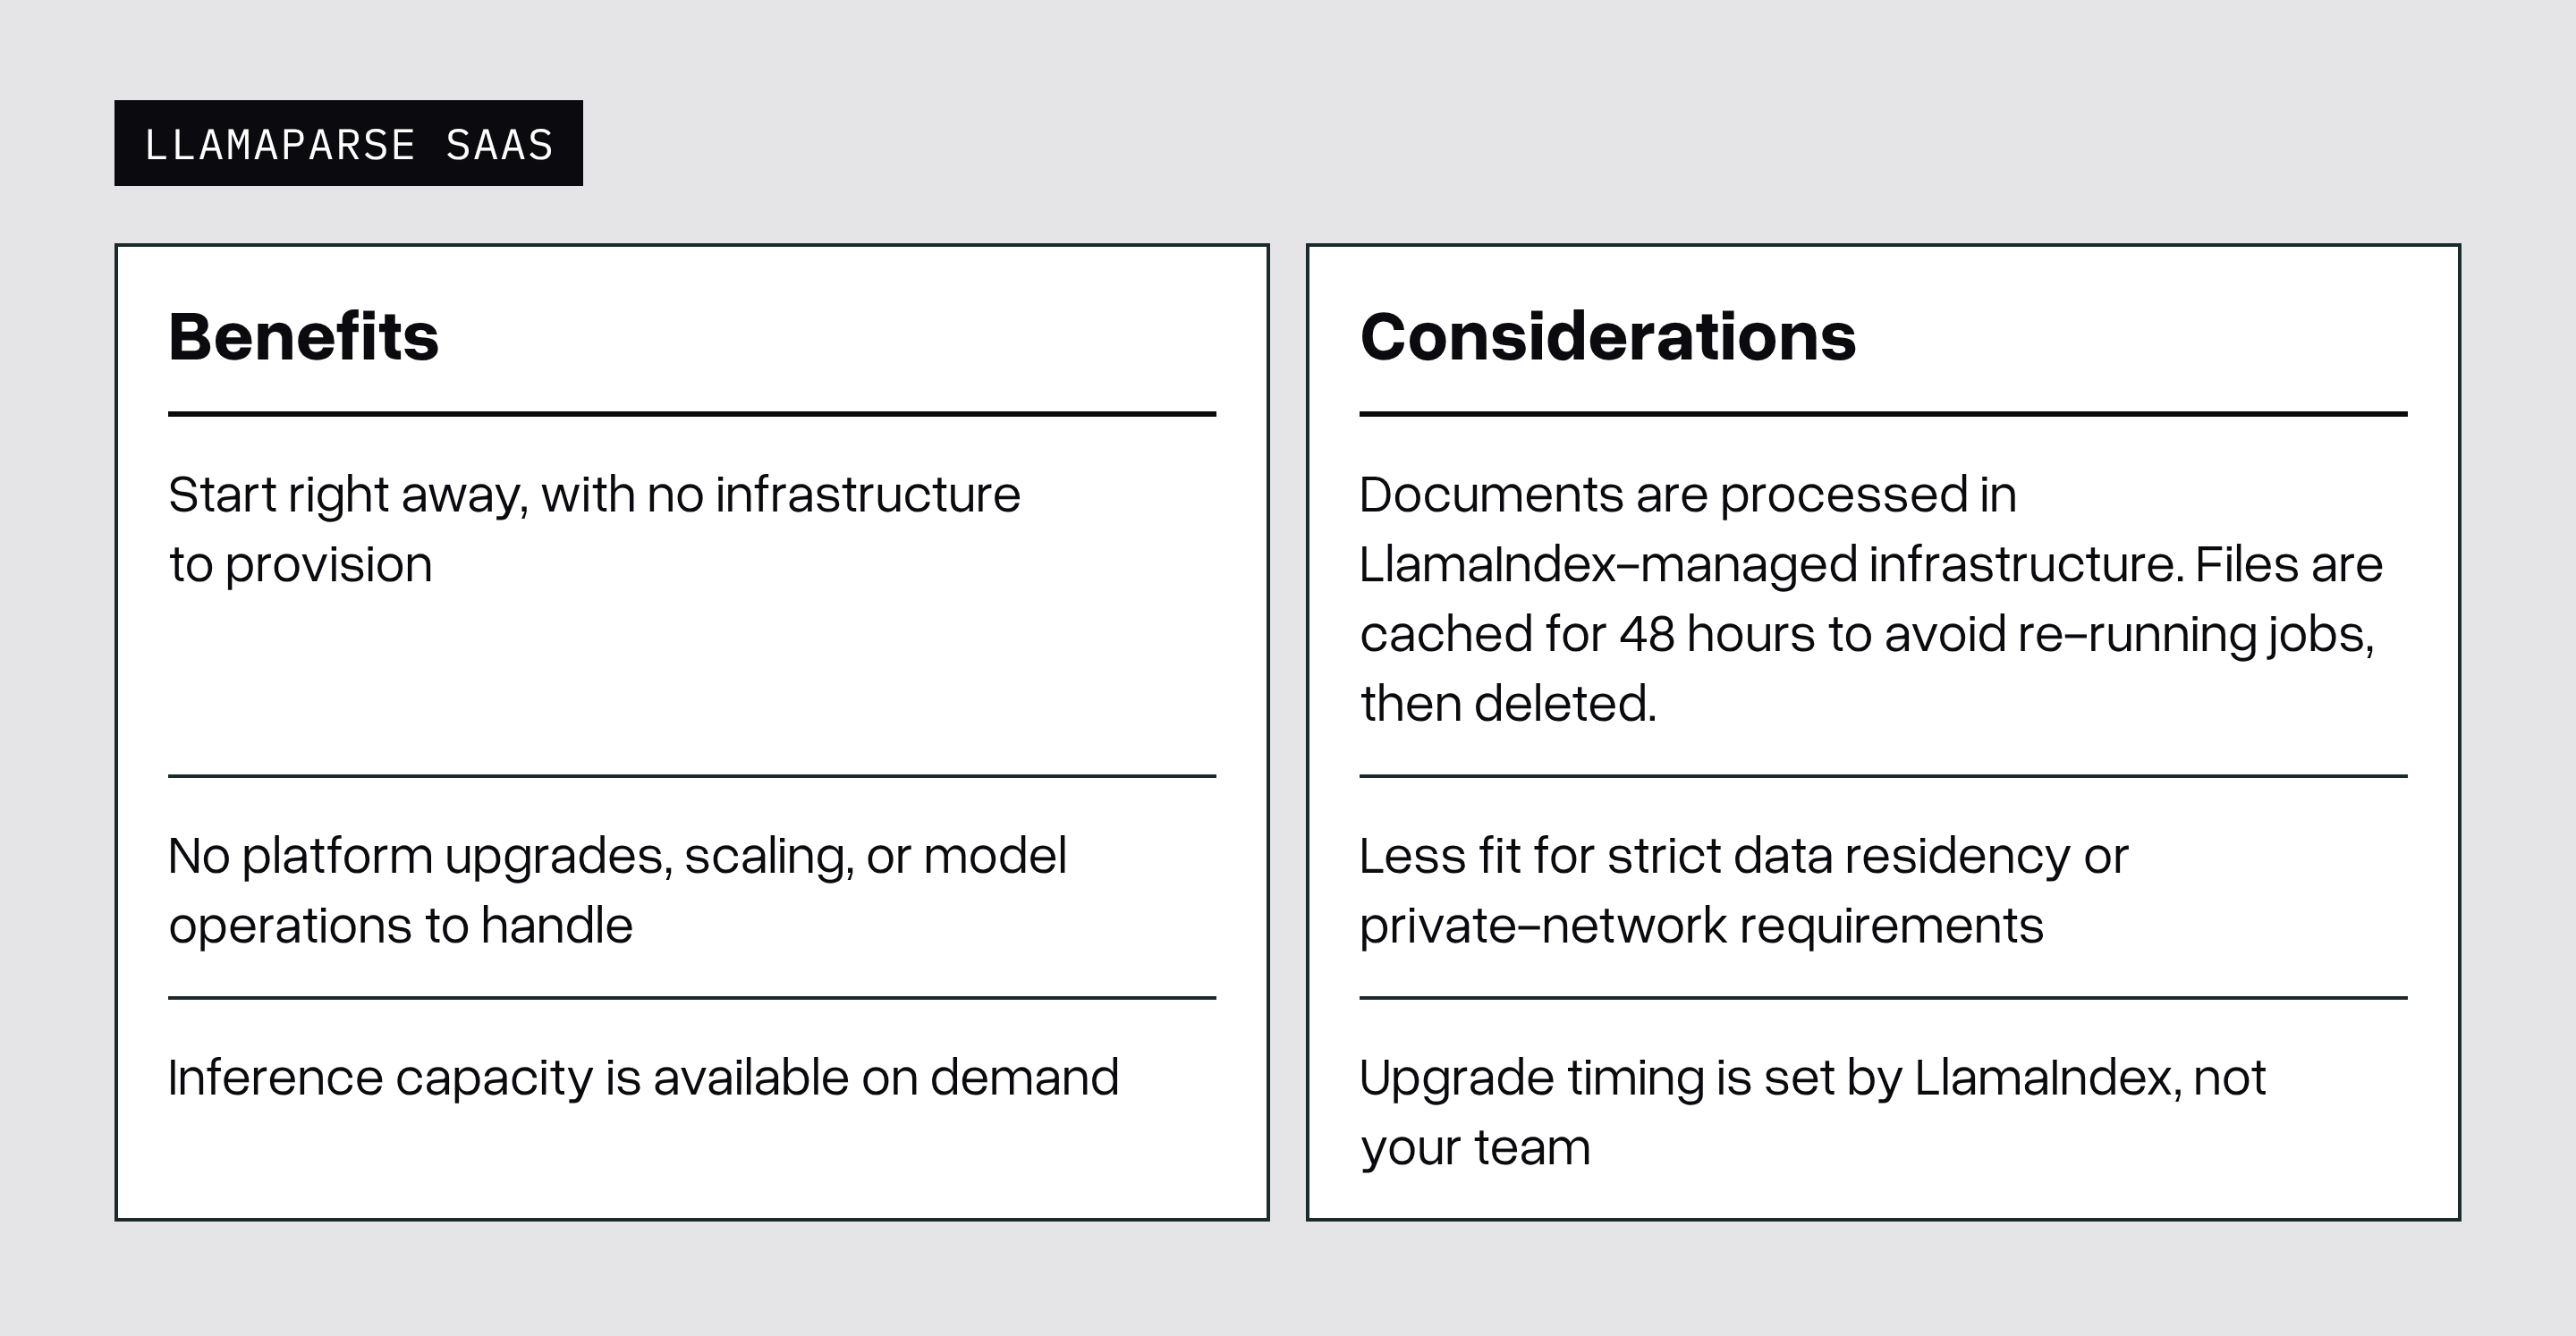
The fastest way to get started. We run the platform, the models, and the GPUs, so your team can go from sign-up to parsing documents in minutes, with nothing to deploy or maintain.
LlamaParse in your VPC (BYOC)
On Enterprise plans, you can run LlamaParse in your own VPC or data center, with documents and processed results stored in your own environment. Where pages are processed depends on which inference option you choose.
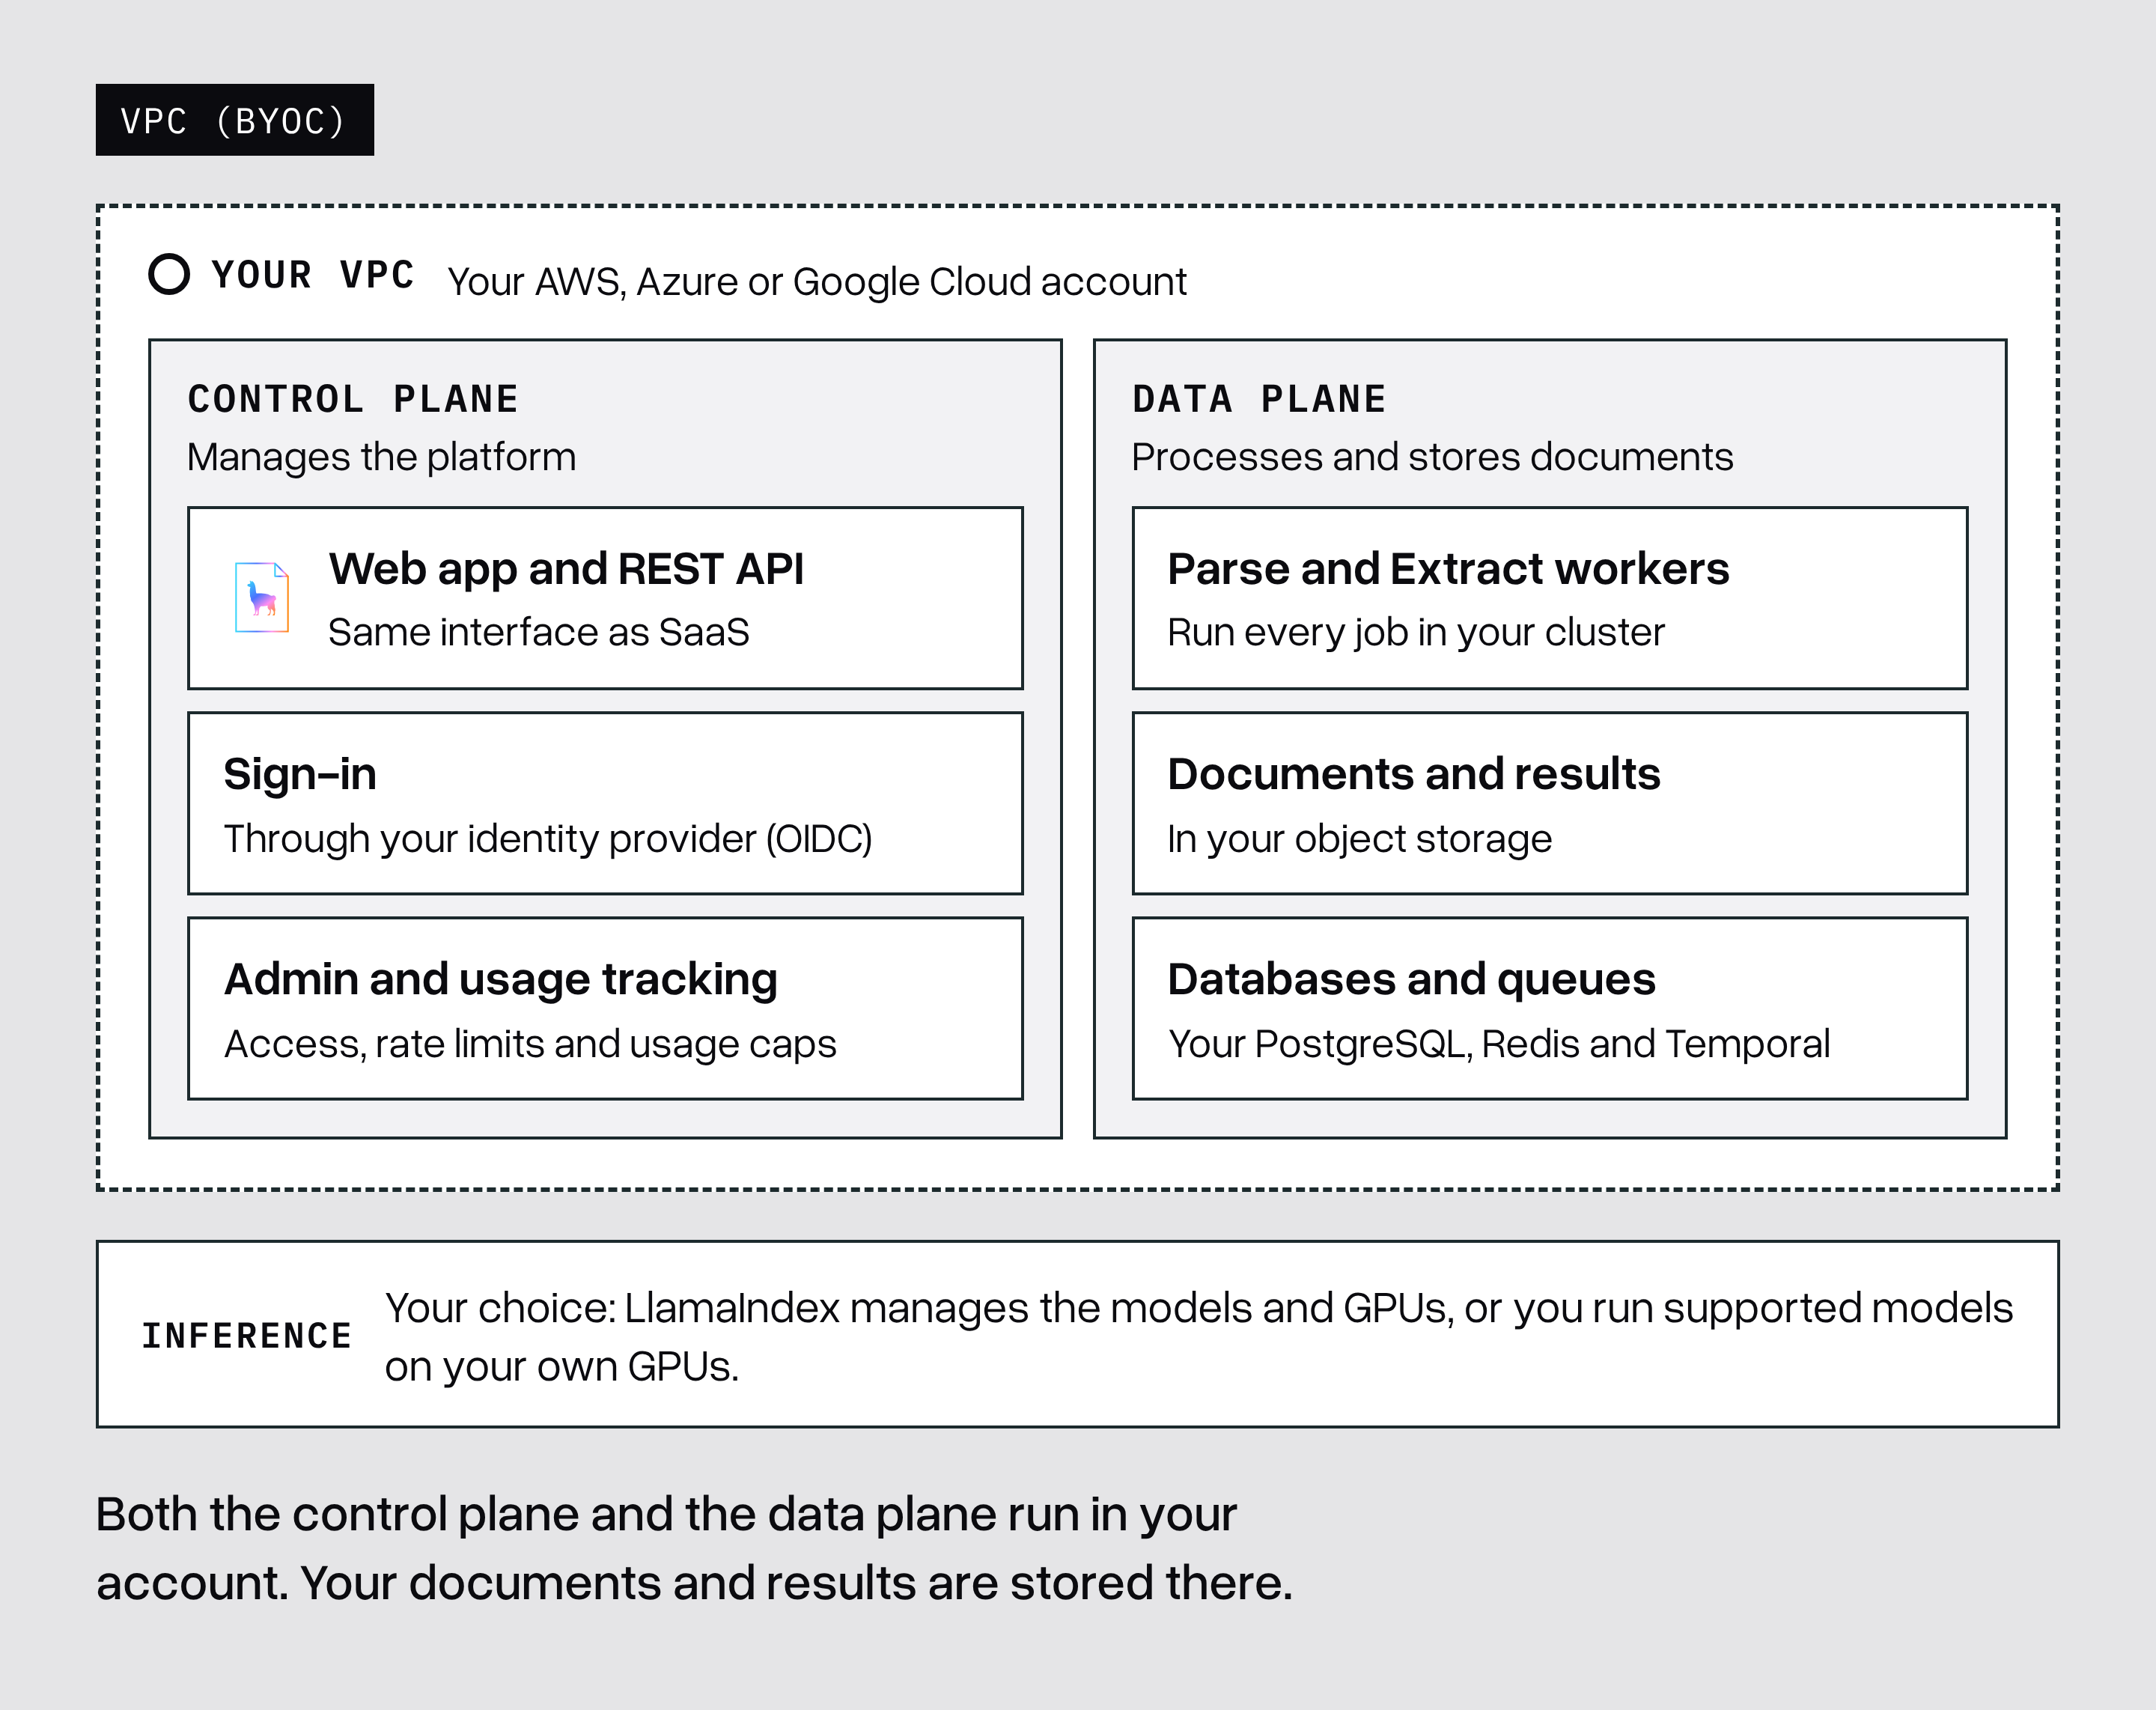
The deployment includes the web UI, REST API, processing workers, and supporting databases. Your team provides the infrastructure, operates the platform, and decides when to upgrade. LlamaParse is installed on Kubernetes using a Helm chart.
You can let LlamaIndex manage inference or operate supported models yourself.
Hybrid: LlamaIndex-managed inference
For teams deploying LlamaParse in their VPC, we recommend a hybrid deployment: your team runs the platform and controls document storage, while LlamaIndex handles the models and GPUs. You keep the platform in your account without taking on model operations.
Managed inference saves your team from provisioning GPU capacity and maintaining model-serving infrastructure. You avoid paying for GPUs that sit idle between jobs, along with the engineering work of keeping models running and scaling them as demand changes.
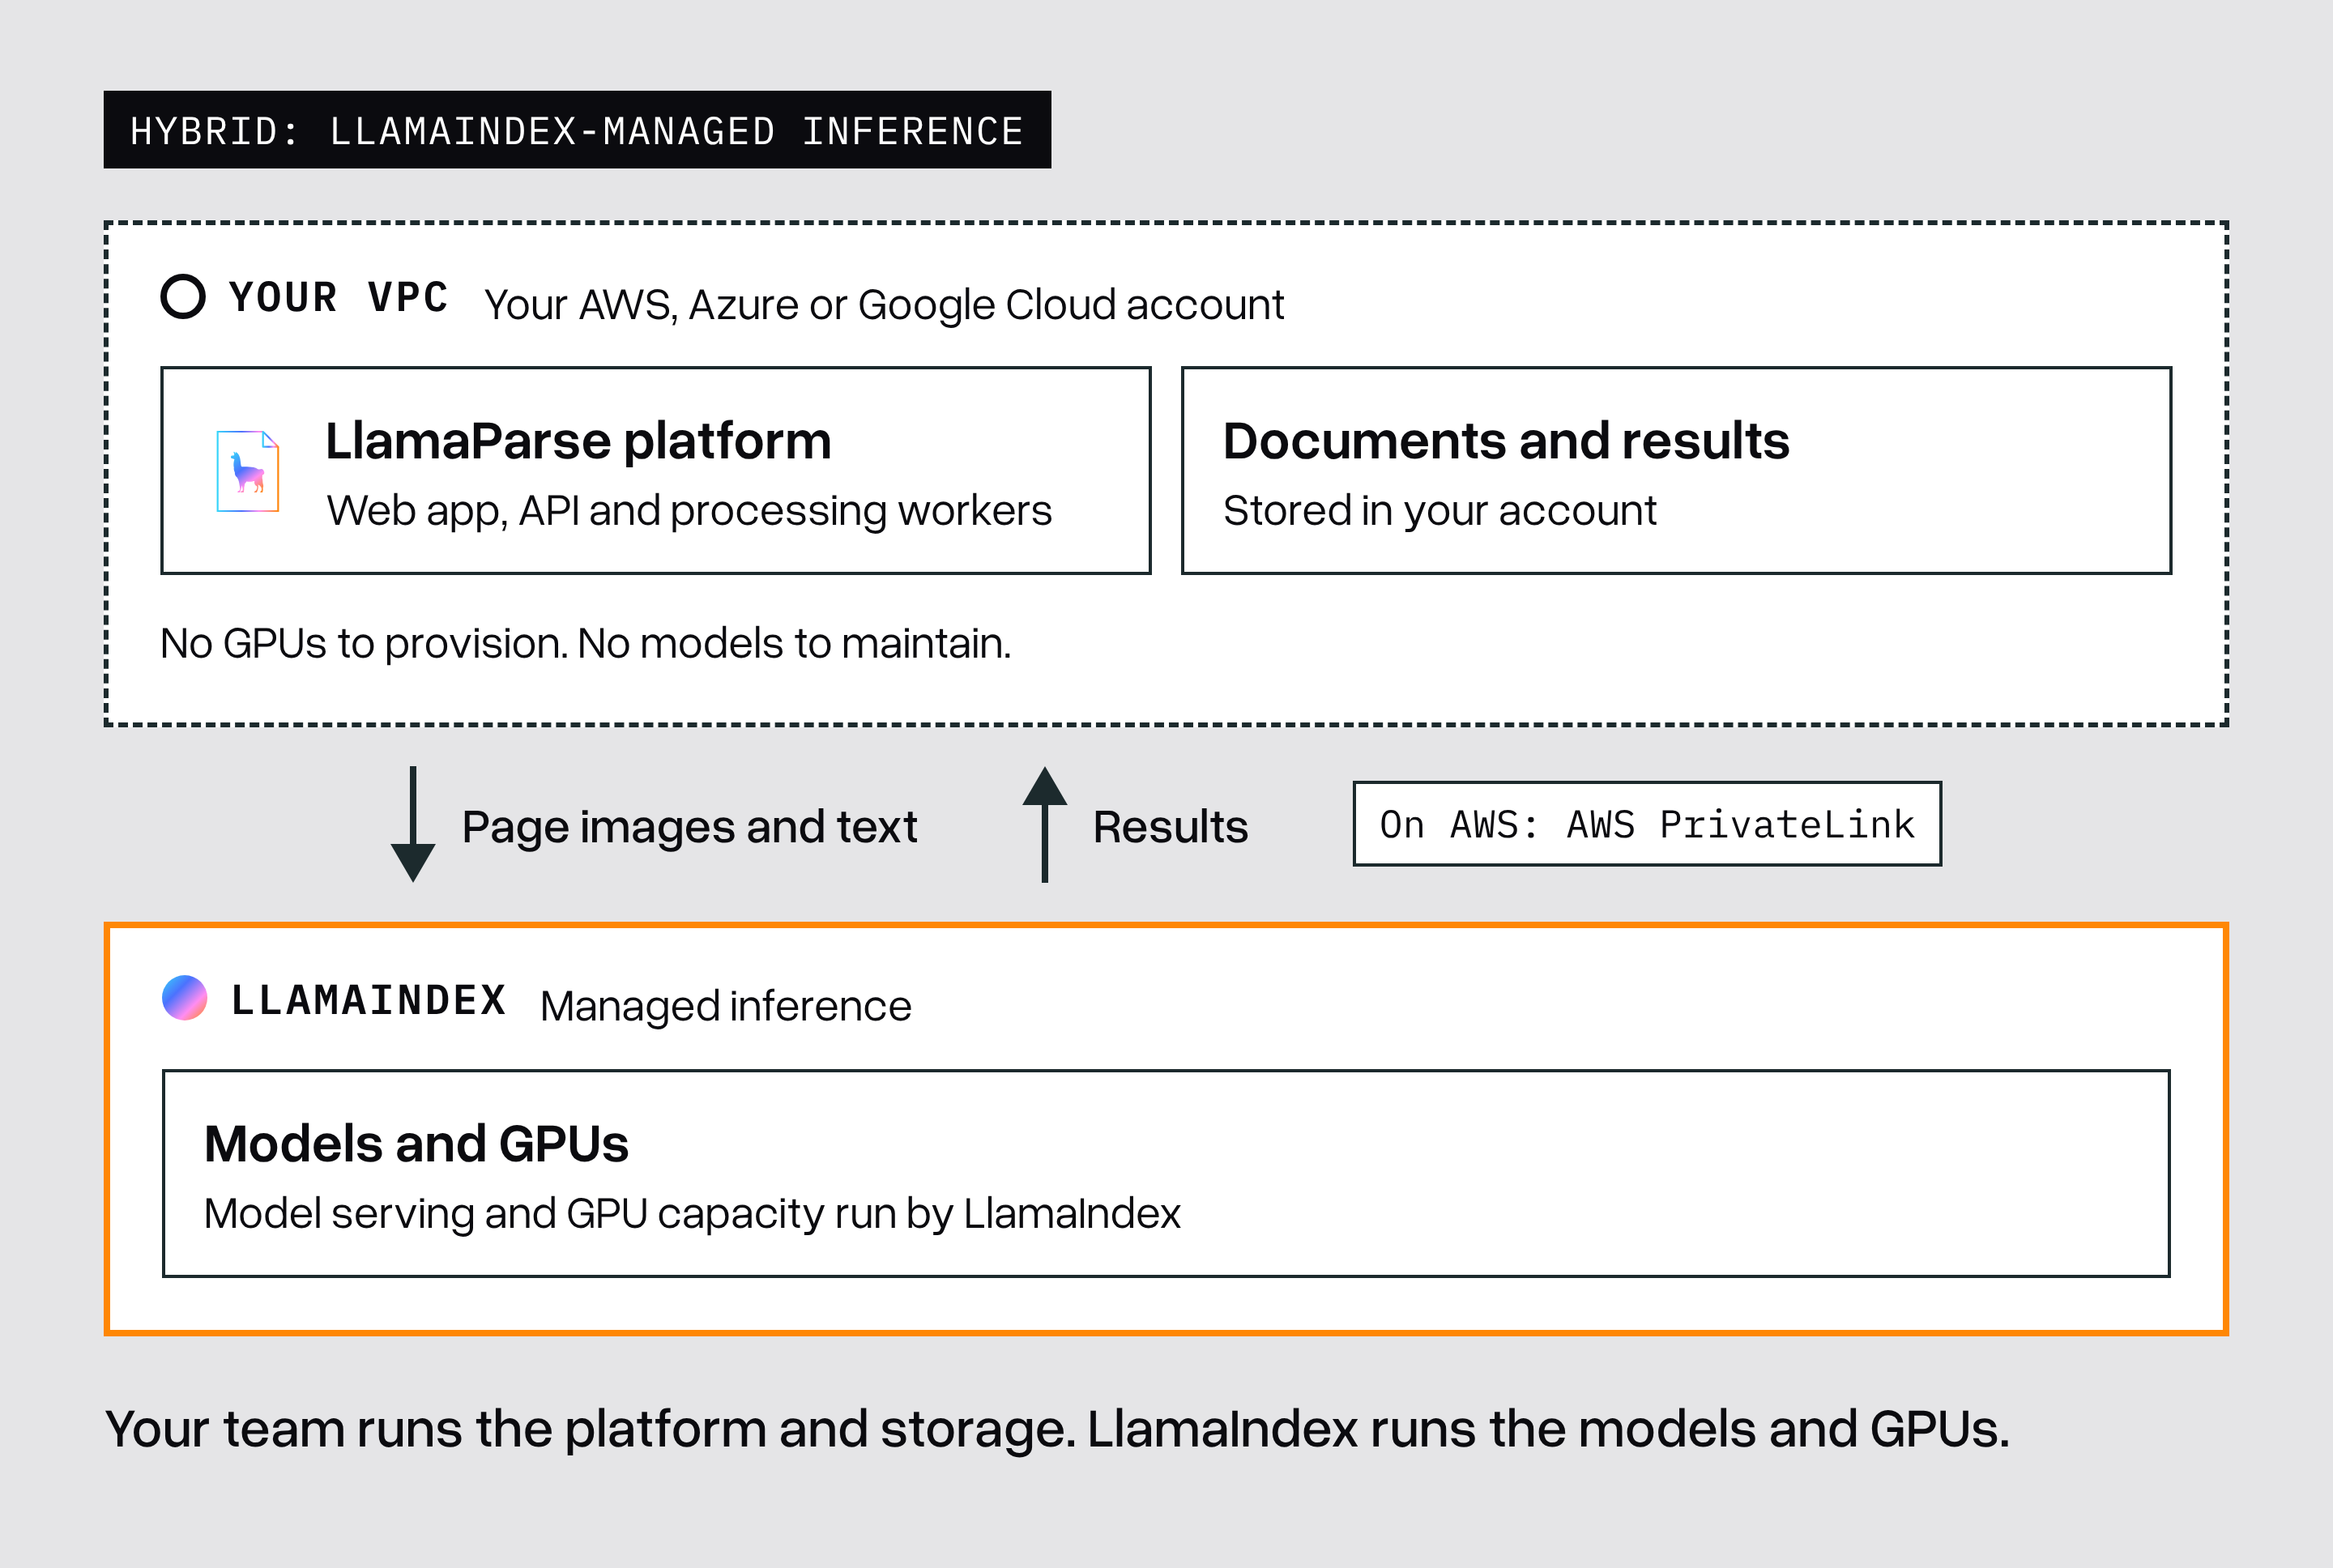
Documents and results remain stored in your account, but page images and text leave your environment for inference. The processing region and connection therefore need to fit your data requirements. On AWS, that connection uses AWS PrivateLink.
Managed inference is also available for on-prem deployments with outbound connectivity. It cannot be used in an air-gapped environment.
Customer-managed inference
If your requirements call for more processing to stay local, you can run supported LlamaIndex models in your own environment.
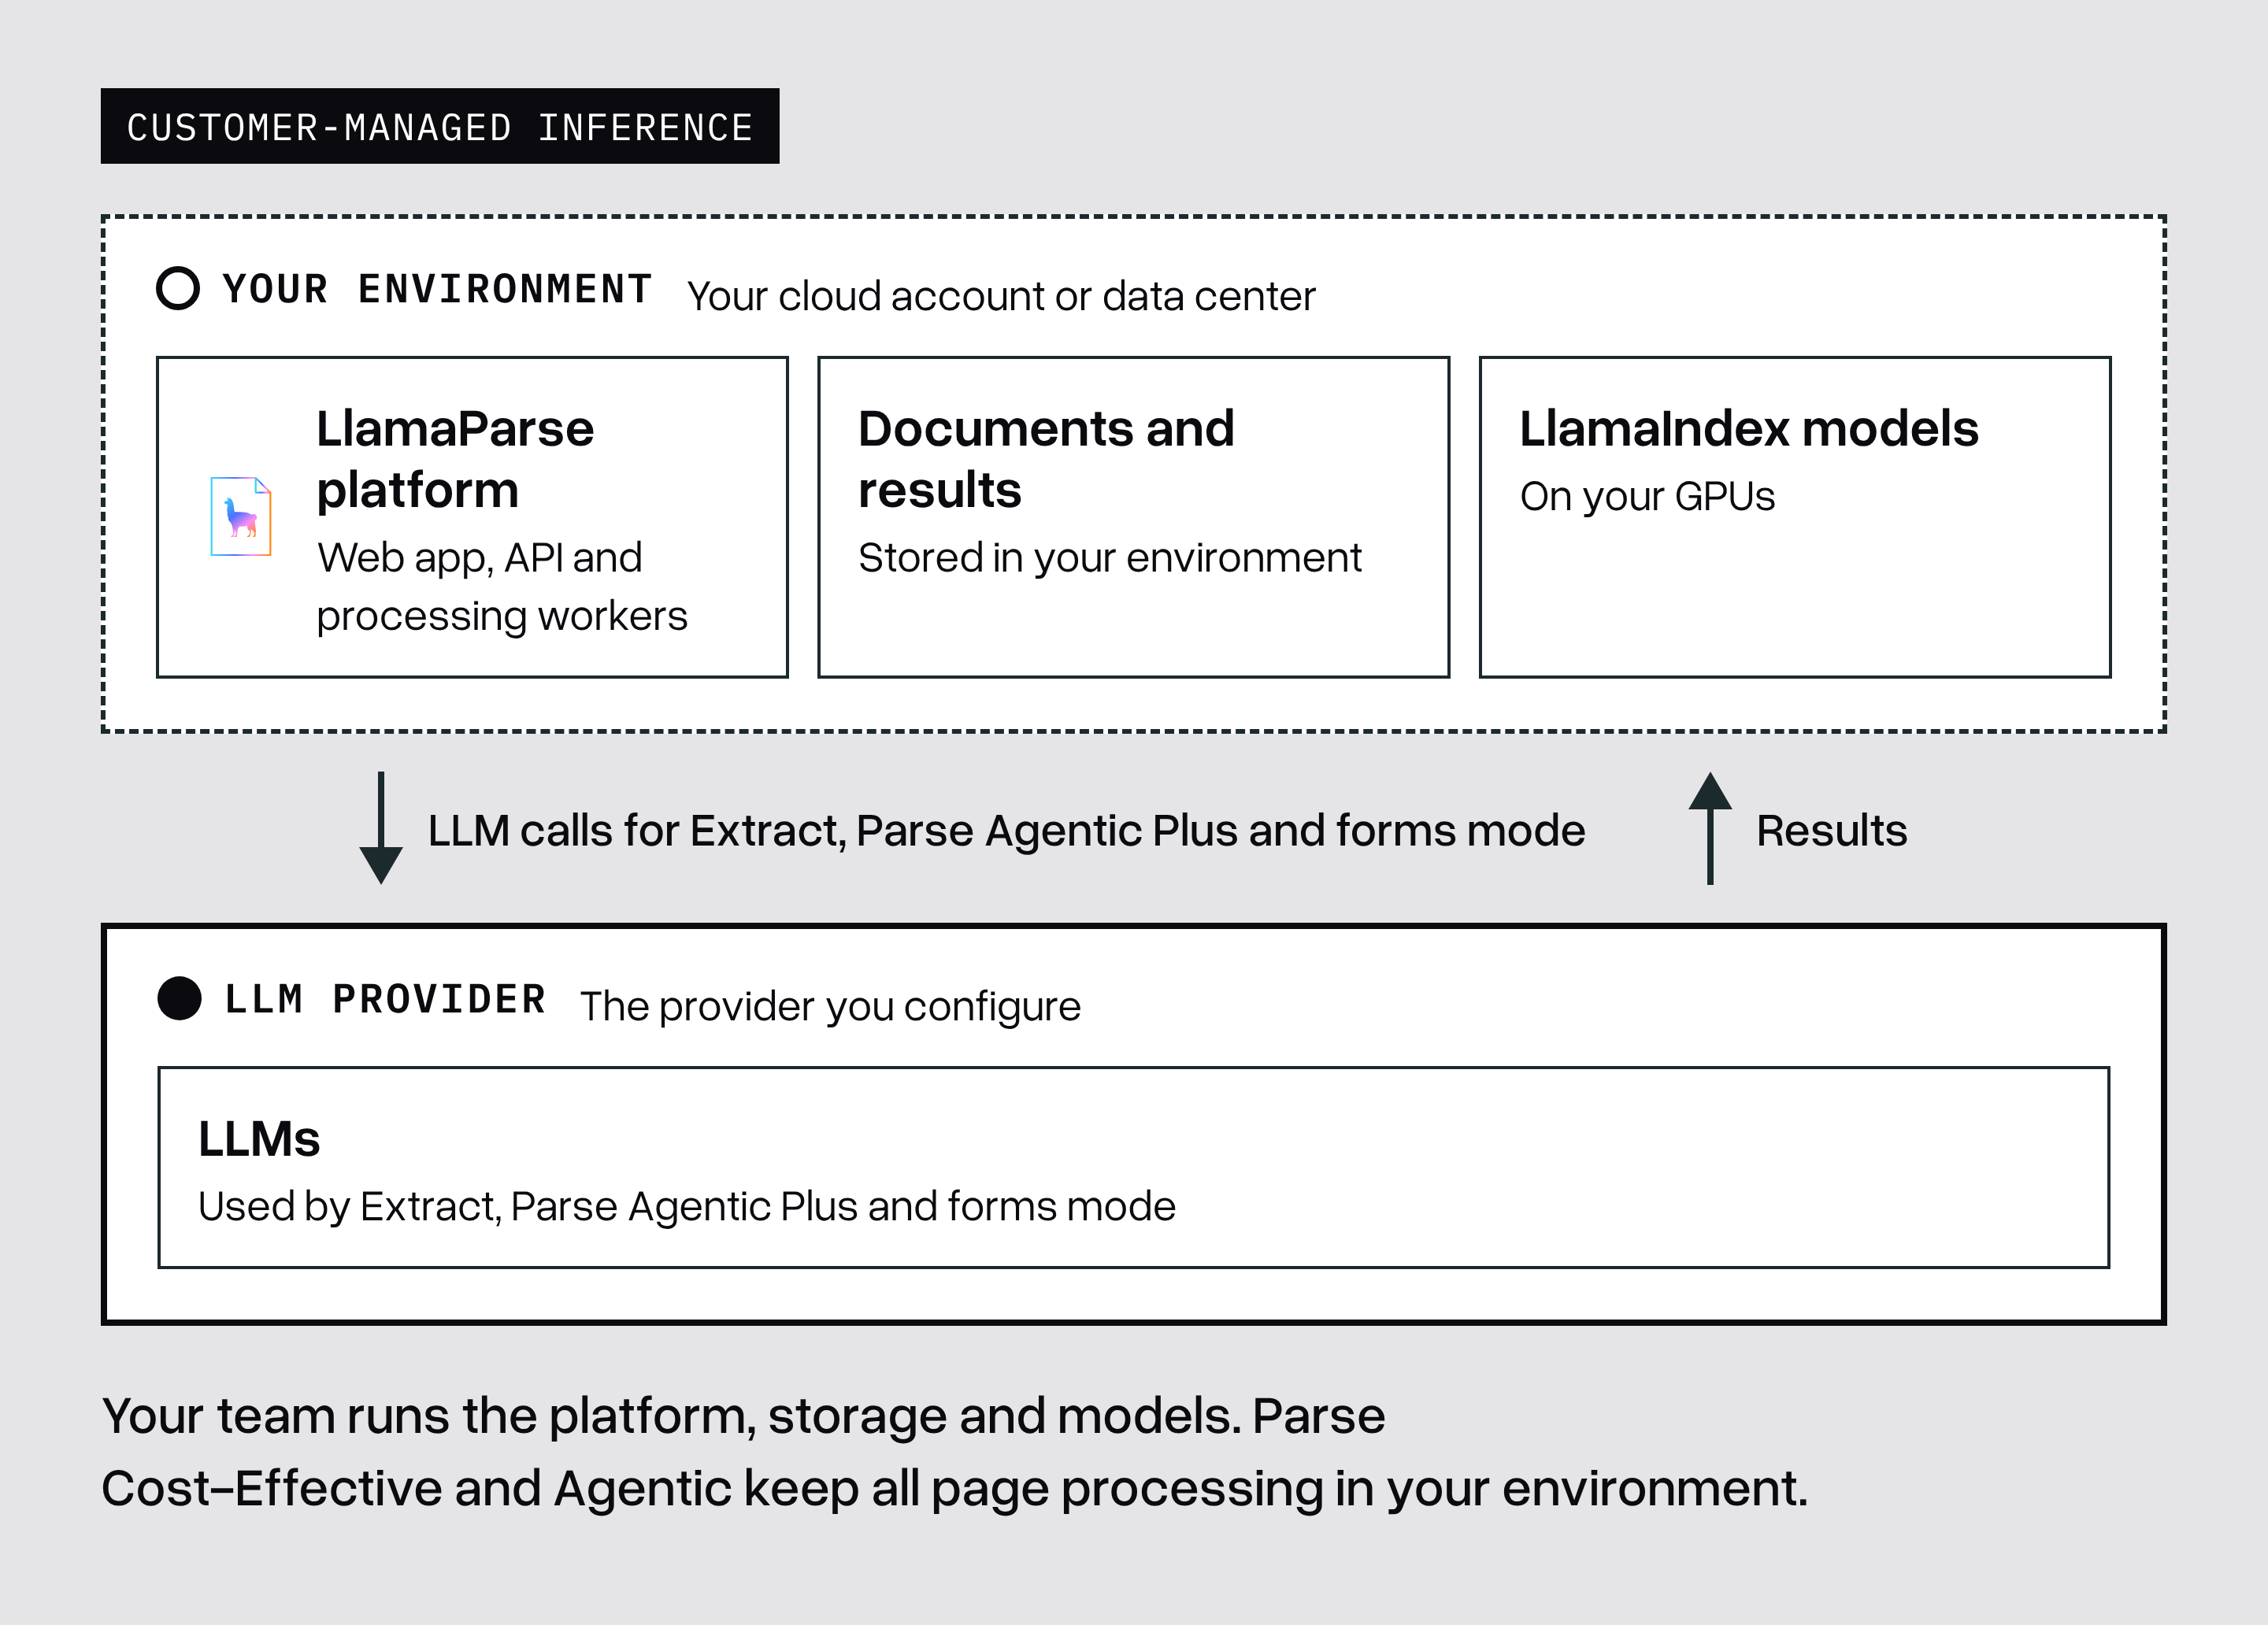
Your team runs the models and provides the GPU capacity, including scaling it as demand changes.This gives you control over the hardware and lets supported processing steps run locally.
What stays local depends on the features you use. With supported models hosted locally, Parse Cost-Effective and Agentic keep all page processing in your environment. Parse Agentic Plus, forms mode, and Extract require external model calls through the provider you configure.
We recommend GPUs for locally hosted models. The right hardware depends on your documents and workload, including content density, GPU type, cloud provider, and whether you’re processing a steady flow or a large backfill.
Choose this approach when operating models locally is a priority and your team can support the infrastructure.
On-prem and air-gapped deployments
LlamaParse runs on a conformant Kubernetes cluster in your data center, using your own storage, databases, and identity provider. Container images, including model images, can be mirrored into your private registry, and the license key is validated without a network connection.
For air-gapped operation, you host supported models on your own GPUs. Parse Cost-Effective and Agentic keep all page processing within your network. Extract, Parse Agentic Plus, and forms mode require outbound model calls. These workflows, along with LlamaIndex managed inference, cannot run in a fully air-gapped environment.
What this means for cost and quality
When comparing costs, include both infrastructure and the work of operating it. Managed inference leaves model operations with LlamaIndex. Hosting models yourself means budgeting for GPUs and the team responsible for keeping them running.
Our team can help assess those costs for your documents and workload.
Processing quality also depends on the models you use. Parse Cost-Effective and Agentic should deliver the same quality with supported models hosted locally as in the managed service. Extract results can differ when your deployment uses different models.
Use representative documents and extraction schemas to evaluate the configuration you plan to run. That gives you a practical view of quality, latency, and cost for your workload.
Getting started
You can start with SaaS or bring LlamaParse into your VPC or data center. If you need the platform in your environment, we’ll help you find an inference setup that fits your data requirements and the infrastructure your team wants to manage.
Try LlamaParse or talk to our team about your deployment.